Sub-frontier LLMs are super exciting again
A long weekend playing with the smaller "Flash" releases from Deepseek, Qwen, and GLM
September 08, 2026
There was a period last year where the opensource models were really lagging all the big frontier closed-source models in terms of capabilities, at least from my experiments. This has changed dramatically with one after another amazing frontier-tier release from the big AI labs in China, Kimi K3 being just incredible. But what really excites me are the models like Deepseek v4 Flash, GLM Flash, Qwen Flash, models that run on self-hostable hardware (DGX Spark seemingly the best performance, but also Strix Halo, Mac Studios, etc) and are within a stones throw of the big expensive and environmentally impacting frontier models. Things that do not require 5000W power budgets, but instead run on sub 200W hardware: AI appliances.
Look at OpenRouter's reasoning leaderboard as of today (9/8/2026)
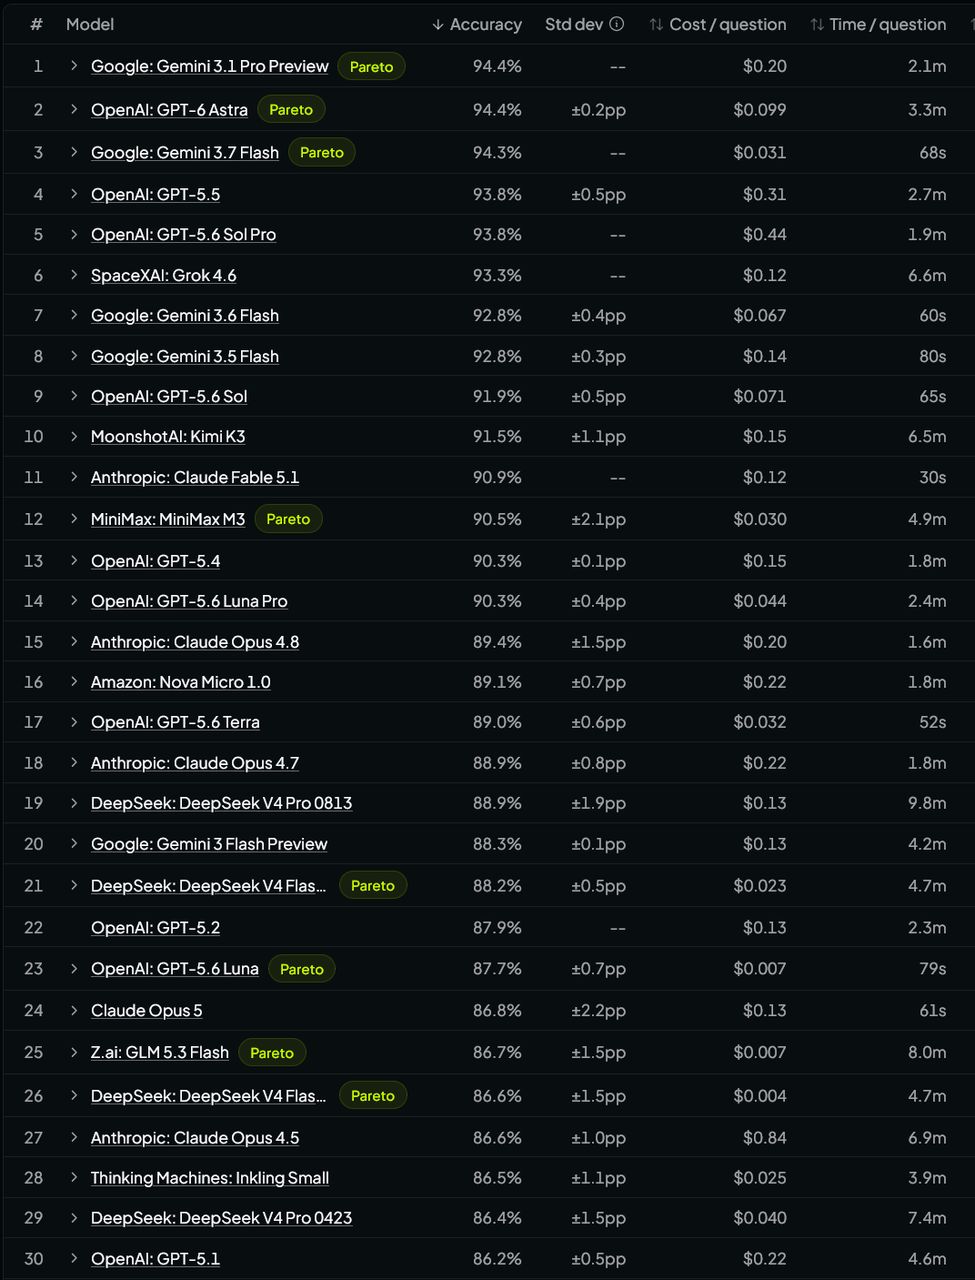
Certainly the release of GPT-6 Astra is the biggest news of the list couple weeks, and its cost per question shows genuine improvements in the number of tokens required to solve a task, but if you scan down the last you've got several Flash models including Google's proprietary but several of the opensource models. As harnesses get better these become increasingly viable to safely solve very complex tasks. My own tinkering this weekend with Qwen 3.8 Flash Next has been extremely positive. With the appropriate tools its reasoning has been good enough to solve very complex multi-step devops and web development tasks with essentially no input beyond the task definition. It successfully built and launched a bunch of services even though it had to deal with my rather draconian AWS IAM setup and a firewall blocking it a few times along the way.
Now with the price of DRAM, GPUs... even PCBs, the dream of "affordable" home AI feels further away from a dollars perspective, but from a technology perspective we are essentially there. No need for endless SaaS AI subscriptions for most kinds of tasks.
I am also very bullish on the supervisor / multi-agent model. Pay OpenRouter for a frontier model like a Kimi K3 to supervise an agent running on local inference engine cycling away with a smaller Flash model. We already do this in a more secure/HIPAA compliant way with Opus supervising Sonnet in Anthropic land. That still ends up somewhat costly, but for home use or industries without regulatory requirements a Kimi / local Qwen split is incredibly appealing.